Operator Guide
This guide covers installation, configuration, TLS setup, and PowerStore CEPA registration.
Installation
Docker (recommended)
docker run -d --name cee-exporter \
  -p 12228:12228 \
  -v ./config.toml:/etc/cee-exporter/config.toml:ro \
  ghcr.io/fjacquet/cee-exporter:latest
Verify it is running:
Binary
Download the latest release for your platform from the GitHub Releases page.
# Linux
chmod +x cee-exporter
./cee-exporter -config config.toml

# Windows (run as Administrator for Win32 EventLog output)
cee-exporter.exe -config config.toml
Build from source
Requires Go 1.27.2. No CGO required.
git clone https://github.com/fjacquet/cee-exporter.git
cd cee-exporter

make build-linux    # Linux/amd64   → ./cee-exporter
make build-windows  # Windows/amd64 → ./cee-exporter.exe
(make build alone runs go build -v ./... to check compilation — it produces no binary.)
Publishers that go through Dell CEE — read this first
If your events arrive via Dell CEE (PowerStore, Unity, VNX), there is one setting that decides whether you receive anything at all, and getting it wrong fails silently: the service runs, the port listens, the array heartbeats, CEE contacts this consumer every ten seconds, and no event is ever published.
CEE will not forward events to a consumer it has not registered, and it only
registers an identity present in a table compiled into its own binary
(CGuidStore, keyed by (friendlyName, facility) → GUID). A self-generated
GUID is refused; CEE then answers the array 0x16 CEPP_NOT_FOUND and the array
discards every event it generates.
So [cepa] is mandatory in that topology:
[cepa]
# Must be a name from CEE's allowlist that is valid for the facility CEE has
# enabled (Audit, for event auditing), and must match the partner id in CEE's
# own EndPoint value. The defaults do NOT work — see below.
friendly_name = "PeerSoftwareCollector"
guid          = "49f4da0f-055f-401c-9f83-a95ce61447f6"
and CEE must be configured with the same name:
HKLM\SOFTWARE\EMC\CEE\CEPP\Audit\Configuration
  EndPoint = PeerSoftwareCollector@http://<this-host>:<port>
The shipped defaults are deliberately ones CEE refuses. These are other
vendors' registered identities and there is no way for a third-party consumer to
obtain its own, so choosing one is a decision with consequences — CEE reports
your consumer under that vendor's name, and it collides with a real deployment
of that product on the same CEE host. See ADR-017 for the reasoning and
cee-worker's docs/cee-partner-allowlist.md for the full table.
Checking it worked
CEE explains a refusal only at Debug=63 — the value is a 6-bit mask, not a
scale, and at the default 1 it says nothing (9 prints less than 3). Set
Debug and Verbose to 63 on the CEE host, restart the CEE service, and look
for:
CEPPAPIWrapper[Audit][<name>][http://…]::Register(): Exit rpcStatus: 0, NtStatus: 0
CEPPAPIWrapper[Audit][<name>][http://…]::HeartBeat(): Response: HB Status: 0 - CEPP_SERVICE_ONLINE
Anything else names the problem:
| CEE says | meaning |
|---|---|
Top node is not RegisterResponse |
the consumer returned an empty body |
unknown or invalid GUID |
that name is not in the allowlist for that facility |
GUID mismatch |
right name, wrong GUID for it |
Substring guid not found |
encoding mismatch (see below) |
HB Status: 1 - CEPP_SERVICE_OFFLINE |
registered, but the heartbeat probe is unanswered |
On Linux that trace goes to stdout (journalctl -u emc_cee). On Windows it goes
to OutputDebugString, not the event log — read it with Sysinternals
DebugView or the dbgcapture.ps1 helper in cee-worker.
Set both back to 0 afterwards; they are diagnostic, not steady-state.
Two things this consumer handles for you
- Encoding. CEE sends the handshake as UTF-16LE to an unrecognised partner and switches to UTF-8 once the identity is allowlisted. Replies mirror the request encoding, so both work.
- The liveness probe. After registering, CEE probes with
<HeartBeatRequest />and needshbStatus=0, or the partner sits OFFLINE and the array receives0x12rather than0x0.
PowerScale/OneFS needs none of this — it speaks CEPA directly to this consumer, with no CEE in the path and no identity to configure.
Configuration reference
All configuration is stored in a TOML file (default: config.toml).
Two environment variables override the config file:
| Variable | Values | Default |
|---|---|---|
CEE_LOG_LEVEL |
debug, info, warn, error |
info |
CEE_LOG_FORMAT |
json, text |
json |
Minimal config (GELF output)
[output]
type          = "gelf"
gelf_host     = "192.168.1.50"   # your Graylog IP
gelf_port     = 12201
gelf_protocol = "tcp"

[listen]
addr = "0.0.0.0:12228"
Full config reference
ListenConfig also accepts the legacy tls = true + cert_file/key_file
combination for backward compatibility: if tls_mode is left unset, that
combination is automatically migrated to tls_mode = "manual" at startup
(main.go's migrateListenConfig). New configs should set tls_mode
directly — the fields below are the current, non-deprecated names.
# Optional: override the hostname embedded in every event.
# Defaults to os.Hostname() if not set.
hostname = ""

[listen]
addr          = "0.0.0.0:12228"  # TCP address and port to listen on
tls_mode      = "off"            # "off" | "manual" | "acme" | "self-signed"
cert_file     = ""               # tls_mode="manual": path to TLS certificate (PEM)
key_file      = ""               # tls_mode="manual": path to TLS private key (PEM)
acme_domains  = []               # tls_mode="acme": domain names for Let's Encrypt
acme_email    = ""               # tls_mode="acme": contact email for Let's Encrypt
acme_cache_dir = "/var/cache/cee-exporter/acme"  # tls_mode="acme": cert cache dir
acme_challenge_addr = ":443"     # tls_mode="acme": TLS-ALPN-01 challenge listener addr; must stay :443

[output]
type           = "gelf"         # Output type — see table below
targets        = []             # type="multi": list of types to fan-out to
evtx_path      = ""             # type="evtx": output path (non-Windows only)
# GELF
gelf_host      = "localhost"
gelf_port      = 12201
gelf_protocol  = "udp"          # "tcp" or "udp"
gelf_tls       = false          # Wrap TCP in TLS (requires gelf_protocol="tcp")
# Syslog (RFC 5424)
syslog_host    = "localhost"
syslog_port    = 514
syslog_protocol = "udp"         # "tcp" or "udp"
syslog_app_name = "cee-exporter"
# Beats / Lumberjack v2
beats_host     = "localhost"
beats_port     = 5044
beats_tls      = false

[queue]
capacity = 100000               # Maximum events buffered in memory
workers  = 4                    # Concurrent writer goroutines

[logging]
level  = "info"                 # debug | info | warn | error
format = "json"                 # json | text

[metrics]
enabled = true                 # Serve /metrics at all
addr    = "0.0.0.0:9228"       # Prometheus /metrics listener
Output types
| Type | Description | Platform |
|---|---|---|
gelf |
GELF 1.1 JSON over UDP or TCP → Graylog | All |
evtx |
Win32 EventLog API on Windows; native .evtx files on all other platforms |
All |
syslog |
RFC 5424 structured syslog over UDP or TCP (RFC 6587 framing for TCP) | All |
beats |
Lumberjack v2 to Logstash / Graylog Beats Input (± TLS) | All |
multi |
Fan-out to any combination of the above | All |
Multi-target example
[output]
type    = "multi"
targets = ["gelf", "syslog"]

gelf_host      = "192.168.1.50"
gelf_port      = 12201
gelf_protocol  = "tcp"

syslog_host    = "syslog.corp.local"
syslog_port    = 514
syslog_protocol = "udp"
Beats (Lumberjack v2) output
Logstash must have a Beats input configured on port 5044. Graylog also supports the Beats protocol via its Beats Input plugin.
EVTX output (rotation and retention)
[output]
type      = "evtx"
evtx_path = "/var/log/cee-exporter/audit.evtx"

flush_interval_s    = 15
max_file_size_mb    = 100
max_file_count      = 10
rotation_interval_h = 24
On Windows this same configuration routes to the Win32 EventLog API and
evtx_path is ignored — the platform decides, there is no separate type.
Every .evtx written on non-Windows hosts before v5.1.0 is unreadable
On Windows, Get-WinEvent -Path on a .evtx this exporter produced
before v5.1.0 returns:
Event Viewer refuses them for the same reason. The cause was in the EVTX encoder (go-evtx before v0.7.0), which wrote a byte combination that occurs nowhere in real Windows event logs.
These files cannot be repaired. The bytes are wrong, the source events are gone, and no conversion exists. If you have been archiving them, that archive is not readable and upgrading does not change it — only files written by v5.1.0 and later are.
What is unaffected: the gelf, syslog and beats outputs, and the
Windows-native evtx output which uses the Win32 Event Log API rather
than writing files. Only the non-Windows .evtx file output is involved.
LogName now resolves to Security. Before v5.1.0, generated records
carried an empty Channel, so Get-WinEvent/Event Viewer resolved LogName
to the empty string — the events belonged to no log. As of v5.1.0 the
channel is passed through, and LogName resolves to Security (measured on
Windows Server 2025: the same three records went from LogName=[] to
LogName=[Security]). This is CI-gated: evtx-oracle asserts
System/Channel == "Security" in the generated XML on every push. Anyone
filtering or routing on LogName should expect Security, not empty, from
files written by v5.1.0 and later.
Triggering rotation manually
On non-Windows platforms, SIGHUP rotates the active .evtx file immediately —
the current chunk is finalised, the file is renamed to a timestamped archive,
and a fresh file is opened.
systemctl reload cee-exporter   # if RestartMode is configured for reload
# or:
kill -HUP "$(pidof cee-exporter)"
Only the EVTX writer implements rotation. Sending SIGHUP while a network
backend is configured is a no-op. SIGHUP is not a Windows signal; the handler
is compiled out there.
Windows Service management
On Windows, cee-exporter.exe can register itself with the Windows Service Control
Manager (SCM) for automatic startup and restart on failure.
Run all service management commands from an Administrator command prompt.
Verification status: since v5.0, the
windowsCI job installs the service, drives it throughsc.exe startandsc.exe stop(confirming it actually reachesRunningandStopped), and uninstalls it — exercising the real SCM lifecycle, not just registration. Crash-restart specifically is not: nothing simulates a crash or observes theOnFailure: "restart"recovery action firing, so that part remains correct by code inspection only. See docs/PROMISES.md.
# Register the service (Delayed Auto-Start, restarts on failure after 5 s)
cee-exporter.exe install -config C:\cee-exporter\config.toml

# Start the service
sc start cee-exporter

# Check status
sc query cee-exporter

# Verify recovery actions are configured
sc qfailure cee-exporter

# Stop the service
sc stop cee-exporter

# Remove the service
cee-exporter.exe uninstall
The service runs as LocalSystem by default. If your CEPA configuration or cert files
require network access to SMB shares, change the service account via services.msc.
Automatic restart behavior
cee-exporter registers with these recovery settings automatically at install:
| Failure | Action | Delay |
|---|---|---|
| First failure | Restart service | 5 seconds |
| Second failure | Restart service | 5 seconds |
| Subsequent | Restart service | 5 seconds |
| Reset failure count after | — | 24 hours |
Linux systemd service
A systemd unit file is included for production deployments:
# From a repo checkout — builds the binary, installs it to
# /usr/local/bin/cee-exporter, and installs the unit:
sudo make install-systemd
sudo install -m 644 config.toml /etc/cee-exporter/config.toml
sudo systemctl enable --now cee-exporter

# Or manually (e.g. from a release tarball, no toolchain on the host):
sudo install -m 755 cee-exporter /usr/local/bin/cee-exporter
sudo install -d -m 755 /etc/cee-exporter
sudo install -m 644 config.toml /etc/cee-exporter/config.toml
sudo install -m 644 deploy/systemd/cee-exporter.service /etc/systemd/system/
sudo systemctl daemon-reload
sudo systemctl enable --now cee-exporter

# Verify:
systemctl status cee-exporter
journalctl -u cee-exporter -f
The unit uses DynamicUser=yes, so there is no system account to create.
systemd provisions a transient UID on each start and creates
/var/log/cee-exporter and /var/lib/cee-exporter with the right ownership.
config.toml must stay world-readable (mode 644), not 640 or 600.
DynamicUser=yes runs the daemon under a transient per-start UID/GID that
belongs to no group but its own, so a group-restricted config file is
unreadable to it and the service crash-loops (Restart=on-failure restarting
a process that immediately exits on a config-read error). This is safe
because config.toml holds no secrets — only paths and settings, including
paths to certificate/key files, never their contents. Anything actually
sensitive (API tokens, ACME account credentials, etc.) belongs in
/etc/cee-exporter/env instead, loaded via EnvironmentFile=- in the unit;
keep that file root-only (600) since it is read by systemd itself before
the process drops privileges, not by the dynamic user.
Prometheus metrics
cee-exporter exposes a Prometheus-compatible /metrics endpoint on port 9228
(separate from the CEPA listener to allow independent TLS configuration):
Available metrics:
| Metric | Type | Description |
|---|---|---|
cee_events_received_total |
Counter | Events received from PowerStore |
cee_events_written_total |
Counter | Events successfully forwarded |
cee_events_dropped_total |
Counter | Events dropped: the queue was full, or a PowerScale event arrived that this build cannot decode yet (see the OneFS limitation below). A non-zero value on a PowerScale publisher means audit records are being acknowledged and discarded |
cee_events_truncated_total |
Counter | Events with at least one field capped before the EVTX writer |
cee_writer_errors_total |
Counter | Writer backend errors |
cee_queue_depth |
Gauge | Current event queue depth |
cee_last_fsync_unix_seconds |
Gauge | Unix timestamp of the last successful fsync to the EVTX file. 0 = none yet; alert when time() - this > flush_interval_s * 2 |
cee_build_info |
Gauge | Always 1; labelled with version and go_version — join on it to correlate other metrics with a release |
cee_cepa_last_request_unix_seconds |
Gauge | Unix timestamp of the last CEPA request from a publisher, labelled remote. Stamped on every PUT — handshake, event batch, or failed payload. Alert when time() - this > 60 |
cee_cepa_registrations_total |
Counter | CEPA handshakes received from a publisher, labelled remote. Either dialect counts: PowerStore's RegisterRequest and PowerScale's CheckFileRequest with action="9". Both are sent per heartbeat, so this climbs steadily on a healthy publisher — it is a heartbeat rate, not a count of distinct registrations. A OneFS event (action="11") is not counted |
cee_cepa_peers_dropped_total |
Counter | Requests from publishers not recorded because the 64-peer cap was reached — increments on every such request, not once per distinct publisher. Non-zero means a real publisher may be missing from the labelled series above |
Publisher liveness
cee_events_received_total sitting at zero is ambiguous: the NAS may be quiet,
or the publisher may have stopped and every event is being lost. Prometheus's
own up does not separate the two — it says this process answers a scrape, not
that anything is still publishing to it. The cee_cepa_* series above answer
that question directly:
- alert: CEEPublisherSilent
  expr: time() - cee_cepa_last_request_unix_seconds > 60
  for: 2m
  annotations:
    summary: "CEE publisher {{ $labels.remote }} has not sent a request in over a minute"
CEE contacts its configured endpoint unprompted every HeartBeatIntervalSecs,
which defaults to 10 (emc_cee_config.xml on Linux; the equivalent registry
value on Windows). 60s is therefore six missed beats. Raise this threshold if
you raise HeartBeatIntervalSecs.
Cold start. The peer table lives in cee-exporter's process memory and
starts empty on every restart. These series only cover publishers seen
since the exporter started — a publisher that was already dead before
startup never gets a series at all, and CEEPublisherSilent cannot fire for
something with no series to compare against. Guard against total silence with:
- alert: CEENoPublishers
  expr: absent(cee_cepa_last_request_unix_seconds)
  for: 5m
  annotations:
    summary: "cee-exporter has seen no CEPA publisher at all since it started"
Where the expected publisher set is known, a per-publisher absent() rule
catches an individual one that never showed up after a restart:
- alert: CEEExpectedPublisherMissing
  expr: absent(cee_cepa_last_request_unix_seconds{remote="10.0.2.250"})
  for: 5m
  annotations:
    summary: "Expected CEE publisher 10.0.2.250 has no series — dead since before the exporter started, or never reachable"
What this does and does not detect. A remote label is a CEE server,
not a NAS Data Mover. The publishing chain is Data Movers → CEE server →
cee-exporter, and one CEE server aggregates many Data Movers. These metrics
catch a CEE host that has gone silent. They do not catch a Data Mover that
stopped publishing into a CEE server that is still healthy — that path stays
green.
Cardinality. The remote label is the source host with the ephemeral port
stripped, capped at 64 distinct publishers. Past the cap, new publishers are
not recorded and cee_cepa_peers_dropped_total increments — if that counter is
non-zero, the labelled series are incomplete. Peers are never expired, because
deleting the series for a publisher that went dark would destroy exactly the
signal the alert depends on.
To cross-check a publisher against CEE's own view, enable CEE debug logging
(Debug and Verbose set to 63 in emc_cee_config.xml, then restart the
service) and read /opt/CEEPack/emc_cee_svc.log.
Example Prometheus scrape config:
Grafana dashboard
dashboards/cee-exporter.json renders the metrics above. It is provisioned
automatically by the monitoring stack in deploy/compose.yaml:
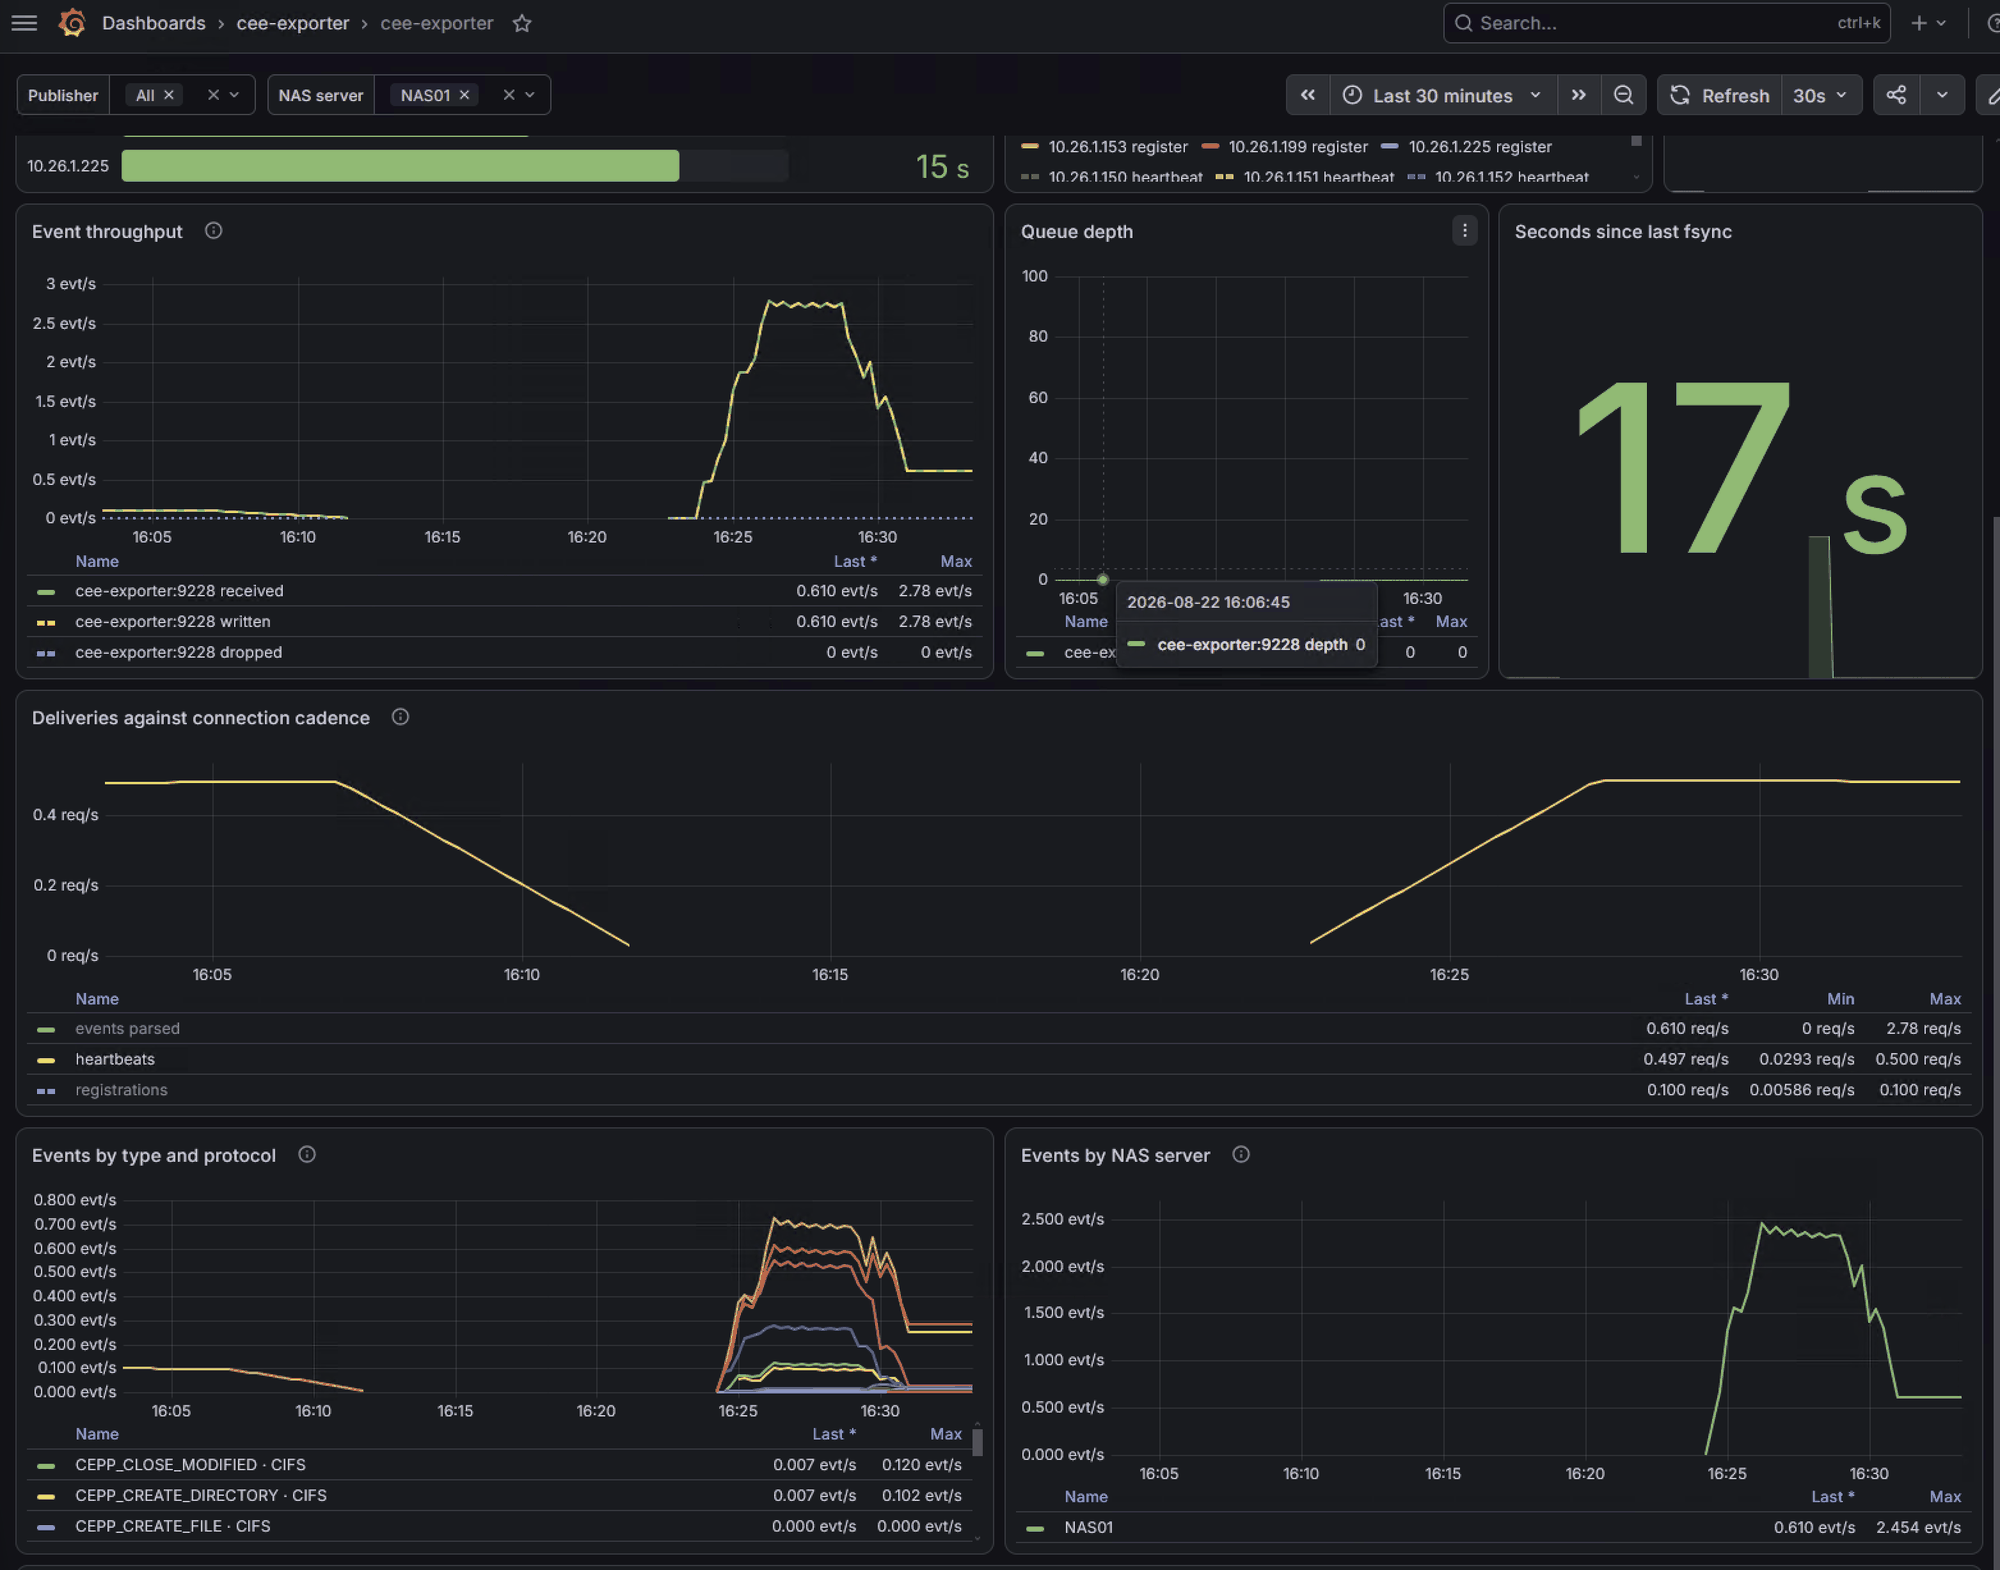
Click for full resolution — the panel labels are unreadable at page width.
The screenshot above is a real capture (Grafana 11.5.1, 2026-08-22) against a
live exporter fed by several CEE publishers on a PowerStore NAS server. The
frame is scrolled to the Diagnostics row, so the two stat panels and the
More metrics row at the top of the dashboard are out of shot. Read it as
proof the panels provision, resolve their datasource and render real data —
not as a performance baseline:
- Both template variables are in use:
PublisherisAll,NAS serveris pinned toNAS01. Every panel below the variables honours that filter, so a second NAS server's traffic would not appear in this frame. - Publisher silence shows one bar per
remotelabel — 15 s for10.26.1.225here. It goes orange at 30 s and red at 60 s. Those thresholds must sit above your CEEHeartBeatIntervalSecsplus jitter — see Publisher liveness — or an idle-but-healthy system will sit permanently yellow. - Handshakes per publisher carries a
registerand aheartbeatseries per publisher, which is how you tell a partner that keeps re-registering (CEE restarting the handshake) from one that is simply heartbeating. - Event throughput peaked at 2.78 evt/s over a ~10-minute burst starting
16:23, with
droppedflat at 0 and queue depth flat at 0. That means the queue was never put under pressure in this window — not that it holds up under a VCAPS batch load.receivedandwrittenoverlap exactly when nothing is being dropped, so one line hides the other; read the legend values, not the shape. - Deliveries against connection cadence answers whether deliveries are driven by filesystem activity or by the connection clock: parsed events (0.610 req/s last, 2.78 peak) rise well above the heartbeat rate, which holds near 0.497 req/s with registrations near 0.100 req/s. An event rate that instead tracks the heartbeat line exactly is CEE redelivering an event it cannot retire, once per heartbeat, forever — see the panel description for the measured case.
- Events by type and protocol breaks the same traffic down per CEPA event
type and access protocol (
CEPP_CLOSE_MODIFIED · CIFSand friends); the legend scrolls, so the visible three are not the whole set. - Seconds since last fsync at 17 s is the age of the last durable write,
not a latency. It sawtooths up to
flush_interval_sand back; alert when it exceeds twice that. Only theevtxwriter fsyncs, so 17 s here means an EVTX file is being written; with a network-only output the underlying gauge never leaves 0 and this panel reads as an epoch-sized age, not as a fault.
No CI job checks this dashboard. Its verification status is tracked in PROMISES.md.
TLS / HTTPS setup
Reminder: The CEPA protocol uses HTTP only. TLS on the cee-exporter CEPA listener (port 12228) does NOT encrypt the PowerStore-to-exporter event channel. TLS here is only meaningful when a TLS-capable reverse proxy sits in front.
cee-exporter supports four TLS modes controlled by the tls_mode config field.
Mode: off (default)
No TLS. Correct for all standard CEPA deployments.
Mode: manual — operator-supplied certificates
Use when you have certificates from an internal CA or a public CA.
[listen]
addr      = "0.0.0.0:12228"
tls_mode  = "manual"
cert_file = "/etc/cee-exporter/server.crt"
key_file  = "/etc/cee-exporter/server.key"
To generate a self-signed certificate for testing:
openssl req -x509 -nodes -newkey rsa:4096 \
  -keyout server.key \
  -out server.crt \
  -days 825 \
  -subj "/CN=cee-exporter" \
  -addext "subjectAltName=DNS:cee-exporter.example.com,IP:192.168.1.10"
Mode: acme — automatic Let's Encrypt certificate
Use when the cee-exporter host has a public DNS name and port 443 is reachable from the internet (or from Let's Encrypt's servers).
[listen]
addr           = "0.0.0.0:12228"
tls_mode       = "acme"
acme_domains   = ["cee-exporter.example.com"]
acme_email     = "ops@example.com"
acme_cache_dir = "/var/cache/cee-exporter/acme"  # must be persistent
cee-exporter starts a TLS-ALPN-01 challenge listener on port 443 in addition to the CEPA listener on 12228. The certificate is automatically renewed 30 days before expiry.
Prerequisites:
- Port 443/TCP must be reachable from the internet
acme_cache_dirmust be on persistent storage (mount a volume if using Docker)- On Linux: the systemd unit must have
AmbientCapabilities=CAP_NET_BIND_SERVICE
There is no staging toggle. tls_mode = "acme" always uses the Let's Encrypt
production directory, which is rate-limited. For development, use
tls_mode = "self-signed" instead.
Mode: self-signed — runtime-generated certificate
Use for air-gapped networks, private deployments, or testing. No network access needed.
cee-exporter generates an ECDSA-P256 certificate at startup (valid 1 year). The certificate is not persisted — it changes on every restart. Clients must disable certificate verification or add the cert to their trust store.
Registering with PowerStore CEPA
CEPA (Common Event Publishing Agent) is the PowerStore mechanism that sends file-system audit events to external consumers over HTTP.
Protocol constraint: The Dell PowerStore CEPA client sends events over plain HTTP only. The endpoint URL in the PowerStore configuration must always use the
http://scheme. Configuringtls = trueon the cee-exporter CEPA listener (port 12228) does not encrypt the PowerStore-to-exporter connection — CEPA will fail to connect if it encounters a TLS handshake. TLS on port 12228 is only useful if a TLS-capable reverse proxy sits in front of cee-exporter.
Prerequisites
- cee-exporter is running and reachable from the PowerStore management network
- Port 12228/TCP is open between PowerStore and the cee-exporter host (firewall rules for HTTP)
Registration steps
- Log in to the PowerStore Manager web UI as an administrator.
- Navigate to Settings → Security → Audit & CEE.
- In the CEE servers section, click Add.
- Enter the cee-exporter endpoint URL using
http://— CEPA supports HTTP only:
- Leave the Username and Password fields empty (cee-exporter uses no authentication).
- Under Events to publish, select all audit event types you want to capture (file create, read, write, delete, ACL change, etc.).
- Click Save.
- PowerStore sends a
RegisterRequestto cee-exporter to confirm connectivity. The daemon logscepa_register_requestat INFO level. -
Verify events are flowing:
Troubleshooting registration
| Symptom | Likely cause |
|---|---|
| PowerStore shows server as Unreachable | Network/firewall blocking port 12228, or cee-exporter not running |
| PowerStore shows TLS handshake error | Certificate SAN mismatch, or cert not imported into PowerStore trust store |
| No events in Graylog after registration | Check gelf_host/gelf_port in config; verify Graylog GELF Input is active |
cepa_parse_error in cee-exporter logs |
Unsupported CEPA payload format — open an issue with the raw payload |
PowerScale (OneFS) — not supported, testable
OneFS forwards protocol audit events by HTTP PUT to a CEE server URI on the
same port this daemon listens on (http://host:12228/cee), and the handler
routes on method, not path — so a cluster can be pointed straight at
cee-exporter with no Dell CEE server in between.
That is a documented transport match, not a working integration. OneFS
names its audited events create/close/delete/rename/set_security,
while pkg/mapper keys on the CEPP_* family PowerStore emits; whether the
CEE payload normalises between them is undocumented and unmeasured, as is
whether OneFS performs the RegisterRequest handshake at all. No OneFS
cluster has ever sent this daemon a packet.
PowerScale verification protocol is the step-by-step procedure for settling it — OneFS Simulator on ESXi first, then a physical cluster — including the packet capture that has to happen before the first PUT, because the forwarder does not replay it.
Health endpoint
GET /health returns a JSON object with operational status. The HTTP status
code is always 200, deliberately — degradation is signalled only by the
"status" field in the body ("ok" or "degraded", the latter once any
events have been dropped). This is a design decision, not a gap: a 503 here
would pull a probed pod out of its Kubernetes Service (readiness) or restart
the container (liveness) exactly when the queue is overflowing, losing
every event instead of the fraction already being dropped, and it would
contradict the CEPA reliability principle that this daemon never tells
PowerStore the endpoint is unreachable. Do not point a liveness/readiness
probe or load-balancer health check at this endpoint expecting a non-200 on
degradation — it will not fire, and it is not supposed to.
For alerting on degradation, scrape cee_queue_depth and
cee_events_dropped_total from /metrics instead (see
Prometheus metrics below) — a rising queue depth or a
nonzero, climbing drop counter is the actual signal. See
docs/PROMISES.md for this endpoint's verification status.
Example response (field names and nesting match pkg/server/health.go's
healthResponse struct exactly):
{
  "status": "ok",
  "uptime_seconds": 9240,
  "queue_depth": 0,
  "events_received_total": 14823,
  "events_written_total": 14823,
  "events_dropped_total": 0,
  "last_event_at": "2026-03-03T08:15:42Z",
  "writer": {
    "type": "gelf",
    "target": "192.168.1.50:12201",
    "healthy": true
  },
  "tls": {
    "enabled": false
  }
}
When TLS is enabled and the certificate is readable, tls additionally
carries cert_expiry (YYYY-MM-DD) and days_remaining, computed fresh on
every request — see the cert-expiry note above; the same computation also
emits the tls_cert_expiry_soon warning log line when fewer than 30 days
remain.
days_remaining distinguishes three states a monitor must not confuse:
| Value | Meaning |
|---|---|
| field absent | No certificate — TLS off, or the cert file is unreadable |
0 |
A certificate exists and expires within 24 hours |
| negative | The certificate has already expired, that many days ago |
Alert on the value, not on the field being falsy. A check written as
if not health.tls.days_remaining fires on the first two rows alike, so it
pages for every plaintext deployment and cannot tell that apart from an
expiry emergency. The value is computed by flooring, so 0 means exactly one
thing and anything below it means expired — the naive int() truncation
reports 0 for a certificate that expired eleven hours ago too.
Graceful shutdown
cee-exporter handles SIGTERM and SIGINT. On receiving a signal it:
- Stops accepting new HTTP connections (30-second drain, plus a fixed 5-second grace period taken only if that drain times out, so worst case is 35 seconds).
- Waits for the event queue to flush.
- Closes the writer connection.